Logistic Regression#
Part of a tutorial on Bayesian regression for survey data with PyMC.
Click here to run this notebook on Colab. For the exercises, use the version with blanks.
# Install nutpie if needed (Colab doesn't have it). Pin ArviZ below 1.0,
# which PyMC 5 needs; otherwise pip upgrades it along with nutpie.

try:
    import nutpie
except ImportError:
    %pip install -q nutpie "arviz<1"
# Get utils.py

from os.path import basename, exists


def download(url):
    filename = basename(url)
    if not exists(filename):
        from urllib.request import urlretrieve

        local, _ = urlretrieve(url, filename)
        print("Downloaded " + local)


download("https://github.com/AllenDowney/SurveyDataPyMC/raw/main/notebooks/utils.py")
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import pymc as pm
import arviz as az

from utils import value_counts, decorate, load_idata_or_sample, subsample

# Show NumPy scalars as 0.36, not np.float64(0.36)
np.set_printoptions(legacy='1.25')
# Make the figures smaller to save some screen real estate
plt.rcParams["figure.dpi"] = 75
plt.rcParams["figure.figsize"] = [6, 3.5]
plt.rcParams["axes.titlelocation"] = "left"
Data#
The dataset we’ll use is an extract from the General Social Survey. The following cell downloads it.
# This dataset is prepared in GssExtract/notebooks/02_make_extract-2022_4.ipynb
# It has been resampled to correct for stratified sampling

DATA_PATH = "https://github.com/AllenDowney/GssExtract/raw/main/data/interim/"
filename = "gss_extract_2022_4.hdf"
download(DATA_PATH + filename)
The file is in HDF format, which we can read using pandas.
gss = pd.read_hdf(filename, "gss")
gss.shape
(72390, 62)
The dataset includes one row for each respondent and one column for each variable.
To demonstrate logistic regression, we’ll use responses to this question.
Generally speaking, would you say that most people can be trusted or that you can’t be too careful in dealing with people?
1	Most people can be trusted
2	Can't be too careful
3	Depends
Here are the counts of the responses – there are a large number of NaN values because not every respondent was asked the question.
value_counts(gss["trust"])
| counts | |
|---|---|
| values | |
| 1.0 | 15783 |
| 2.0 | 24890 |
| 3.0 | 1966 |
| NaN | 29751 |
Although there are three possible responses, we’ll treat this as a binary variable.
So we’ll recode the data so 1 means “most people can be trusted” and 0 means either of the other responses.
gss["y"] = gss["trust"].replace([1, 2, 3], [1, 0, 0])
value_counts(gss["y"])
| counts | |
|---|---|
| values | |
| 0.0 | 26856 |
| 1.0 | 15783 |
| NaN | 29751 |
Here’s what the percentage of affirmative responses looks like over time.
time_series = gss.groupby("year")["y"].mean() * 100
time_series.plot(style="o")
decorate(ylabel="percent", title="Can people be trusted?")
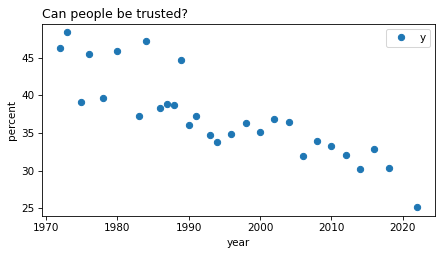
Sadly, levels of trust have been declining in the US for decades.
Who is most trusting?#
Who do you think is most trusting, Democrats, Republicans, or independents? To find out, we’ll use another GSS variable, which contains responses to this question:
Generally speaking, do you usually think of yourself as a Republican, Democrat, Independent, or what?
0	Strong democrat
1	Not very strong democrat
2	Independent, close to democrat
3	Independent (neither, no response)
4	Independent, close to republican
5	Not very strong republican
6	Strong republican
7	Other party
To simplify the analysis, we’ll consider just three groups, Democrats (strong or not), Independent (leaning either way) and Republican (strong or not).
party_map = {
    0: 0,
    1: 0,
    2: 1,
    3: 1,
    4: 1,
    5: 2,
    6: 2,
    7: np.nan,
}

gss["partyid3"] = gss["partyid"].replace(party_map)
value_counts(gss["partyid3"])
| counts | |
|---|---|
| values | |
| 0.0 | 25439 |
| 1.0 | 26705 |
| 2.0 | 18338 |
| NaN | 1908 |
We’ll use this dictionary to map from codes to names.
party_names = {
    0: "Democrat",
    1: "Independent",
    2: "Republican",
}
The following table shows how the percentages in each group have changed over time.
table = (
    gss.pivot_table(index="year", columns="partyid3", values="y", aggfunc="mean")
).rename(columns=party_names) * 100

table.iloc[:10]
| partyid3 | Democrat | Independent | Republican |
|---|---|---|---|
| year | |||
| 1972 | 41.055341 | 48.325359 | 59.146341 |
| 1973 | 43.001686 | 49.295775 | 59.292035 |
| 1975 | 33.571429 | 40.525328 | 44.623656 |
| 1976 | 41.401274 | 44.383057 | 55.974843 |
| 1978 | 34.542587 | 44.649446 | 41.087613 |
| 1980 | 44.144144 | 44.878957 | 49.722222 |
| 1983 | 30.000000 | 41.403509 | 45.679012 |
| 1984 | 42.407407 | 48.098859 | 52.162162 |
| 1986 | 32.342657 | 37.894737 | 47.783251 |
| 1987 | 33.455882 | 38.336347 | 49.403341 |
Here’s what the columns look like as time series.
colors = ["C0", "C4", "C3"]
table.plot(color=colors)
decorate(ylabel="percent", title="Percent saying people can be trusted")
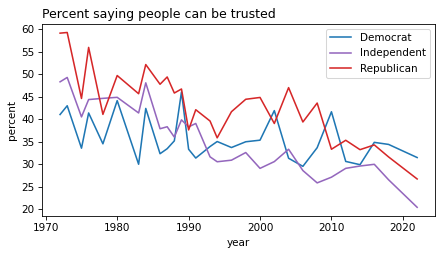
It looks like Republicans were the most trusting group, historically, but that might be changing.
Logistic Regression#
We’ll use logistic regression to model changes in these responses over time and differences between groups.
The fundamental idea of logistic regression is that each observation unit – like a survey respondent – has some latent propensity to choose one of two options, and we assume:
The latent propensities,
z[i], are a linear function of explanatory variables.The probability a respondent chooses a particular option is
expit(z[i]).
Where expit is the function that maps from log-odds to probability (defined in scipy.special, also available from PyMC as pm.math.sigmoid).
As a first example, we’ll make a model with year as an explanatory variable, so we’ll assume
z = alpha + beta * year
In a minute we’ll see how to represent this model in PyMC, but first let’s prepare the data.
We’ll select the rows with valid data for the response variable and year.
data = gss.dropna(subset=["y", "year"])
data = subsample(data)
data.shape
(42639, 64)
And we’ll extract the values as NumPy arrays.
y = data["y"].to_numpy()
year = data["year"].to_numpy()
We’ll shift year so it’s centered at its mean (and we’ll see why later).
year_shift = data["year"].mean()
year = year - year_shift
Now here’s the key idea of PyMC (and MCMC in general): if you can describe the data-generating process, the sampler can generate a sample from the posterior distribution of the parameters.
In the next cell, fill in the missing parts of the model. If you run the sampler before you fill them in, it fails with an error like All initialization points failed.
# Fill this in

with pm.Model() as logistic_model:

    # TODO: Choose priors for alpha and beta
    alpha = pm.Normal("alpha", mu=0, sigma=1)
    beta = pm.Normal("beta", mu=0, sigma=1)

    # TODO: Define the linear predictor
    z = 0

    # TODO: Apply the sigmoid function to get probabilities
    p = 0

    # TODO: Define the likelihood using a Bernoulli distribution
    y_obs = pm.Bernoulli("y_obs", p=p, observed=y)
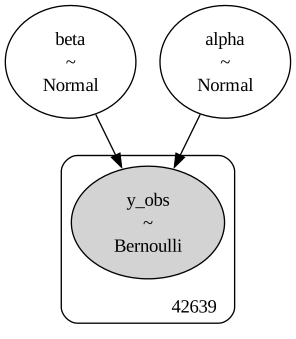
Objects created in the context manager are registered as elements of the model. Here’s a graphical representation of the model.
pm.model_to_graphviz(logistic_model)
The posterior distribution#
The function that samples from the posterior distribution is called sample.
with logistic_model:
    idata = pm.sample(draws=500, tune=500)
draws indicates the number of samples we want from each chain.
tune is the number of samples used to tune the chains before we start saving values.
For the workshop, we’ll use the following function, which loads the results if they are already saved, or runs the sampler otherwise.
filename = "logistic_model_idata.nc"
idata = load_idata_or_sample(logistic_model, filename, draws=500, tune=500)
Loaded idata from logistic_model_idata.nc
The result is an ArviZ InferenceData object, which contains several groups of data stored as xarray Dataset objects.
idata
-
<xarray.Dataset> Size: 36kB Dimensions: (chain: 4, draw: 500) Coordinates: * chain (chain) int64 32B 0 1 2 3 * draw (draw) int64 4kB 0 1 2 3 4 5 6 7 ... 493 494 495 496 497 498 499 Data variables: alpha (chain, draw) float64 16kB ... beta (chain, draw) float64 16kB ... Attributes: created_at: 2026-10-21T13:40:14.361411+00:00 arviz_version: 0.23.4 inference_library: nutpie inference_library_version: 0.16.11 sampling_time: 6.847053050994873 tuning_steps: 500 -
<xarray.Dataset> Size: 282kB Dimensions: (chain: 4, draw: 500) Coordinates: * chain (chain) int64 32B 0 1 2 3 * draw (draw) int64 4kB 0 1 2 3 4 ... 495 496 497 498 499 Data variables: (12/20) depth (chain, draw) uint64 16kB ... maxdepth_reached (chain, draw) bool 2kB ... step_size (chain, draw) float64 16kB ... transformation_update_id (chain, draw) int64 16kB ... step_size_bar (chain, draw) float64 16kB ... mean_tree_accept (chain, draw) float64 16kB ... ... ... fisher_distance (chain, draw) float64 16kB ... transformation_index (chain, draw) int64 16kB ... diverging (chain, draw) bool 2kB ... divergence_draw (chain, draw) uint64 16kB ... divergence_message (chain, draw) float64 16kB ... divergence_energy_error (chain, draw) float64 16kB ... Attributes: created_at: 2026-10-21T13:40:14.344033+00:00 arviz_version: 0.23.4 -
<xarray.Dataset> Size: 682kB Dimensions: (y_obs_dim_0: 42639) Coordinates: * y_obs_dim_0 (y_obs_dim_0) int64 341kB 0 1 2 3 4 ... 42635 42636 42637 42638 Data variables: y_obs (y_obs_dim_0) int64 341kB ... Attributes: created_at: 2026-10-21T13:40:14.360673+00:00 arviz_version: 0.23.4 inference_library: pymc inference_library_version: 5.28.5 -
<xarray.Dataset> Size: 36kB Dimensions: (chain: 4, draw: 500) Coordinates: * chain (chain) int64 32B 0 1 2 3 * draw (draw) int64 4kB 0 1 2 3 4 5 6 7 ... 493 494 495 496 497 498 499 Data variables: alpha (chain, draw) float64 16kB ... beta (chain, draw) float64 16kB ... Attributes: created_at: 2026-10-21T13:40:14.335225+00:00 arviz_version: 0.23.4 -
<xarray.Dataset> Size: 658kB
Dimensions:                   (chain: 4, draw: 500)
Coordinates:
  * chain                     (chain) int64 32B 0 1 2 3
  * draw                      (draw) int64 4kB 0 1 2 3 4 ... 495 496 497 498 499
Data variables: (12/20)
    depth                     (chain, draw) uint64 16kB ...
    maxdepth_reached          (chain, draw) bool 2kB ...
    step_size                 (chain, draw) float64 16kB ...
    transformation_update_id  (chain, draw) int64 16kB ...
    step_size_bar             (chain, draw) float64 16kB ...
    mean_tree_accept          (chain, draw) float64 16kB ...
    ...                        ...
    fisher_distance           (chain, draw) float64 16kB ...
    transformation_index      (chain, draw) int64 16kB ...
    diverging                 (chain, draw) bool 2kB ...
    divergence_draw           (chain, draw) uint64 16kB ...
    divergence_message        (chain, draw) <U49 392kB ...
    divergence_energy_error   (chain, draw) float64 16kB ...
Attributes:
    created_at:     2026-10-21T13:40:14.355672+00:00
    arviz_version:  0.23.4
ArViz provides a variety of functions for processing and visualizing the results.
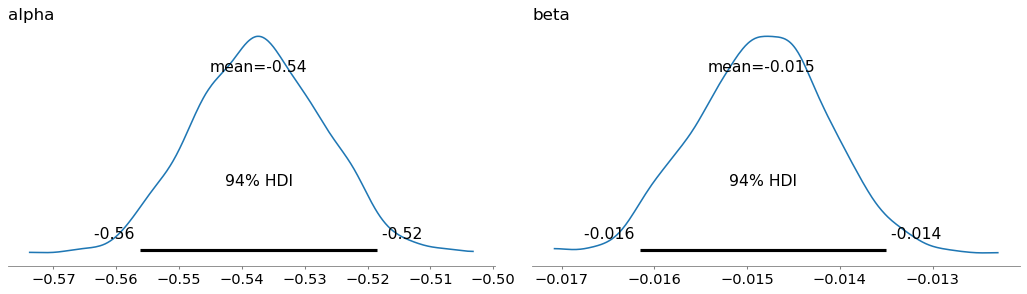
In this example, the primary thing we’re interested in is the posterior distributions of the coefficients alpha and beta.
az.plot_posterior(idata)
decorate()
Comparing Prior with Posterior#
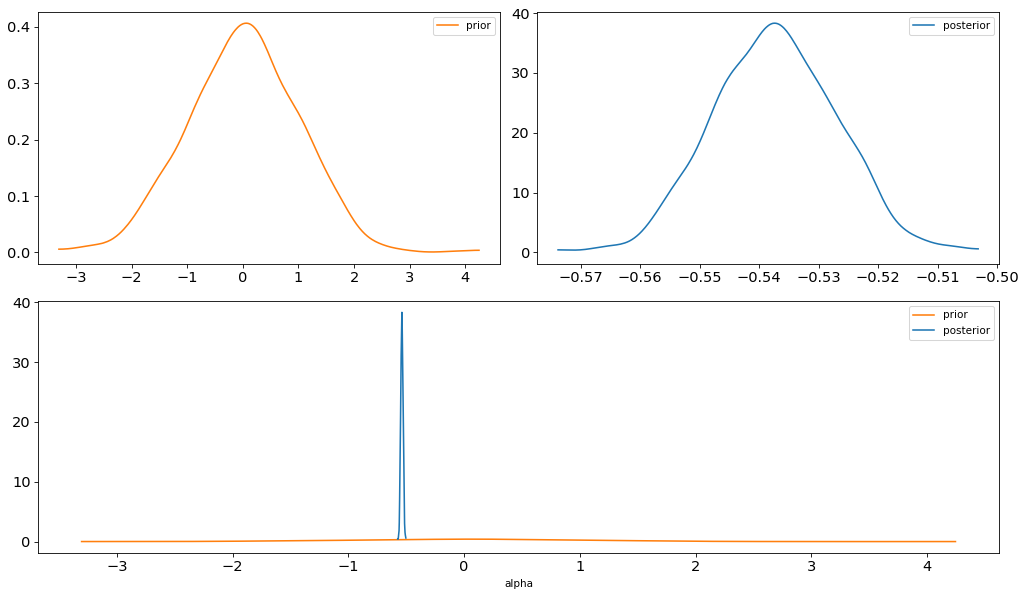
To see what we learned from the data, we can compare the prior and posterior distributions of the coefficients.
sample_prior_predictive runs the model forward to generate samples from the prior distribution.
with logistic_model:
    idata_prior = pm.sample_prior_predictive(draws=1000)
Sampling: [alpha, beta, y_obs]
The result is another InferenceData object.
It will be convenient to put all of the samples in one object.
idata.extend(idata_prior)
Now we can compare the prior and posterior distributions.
az.plot_dist_comparison(idata, var_names=["alpha"])
decorate()
az.plot_dist_comparison(idata, var_names=["beta"])
decorate()
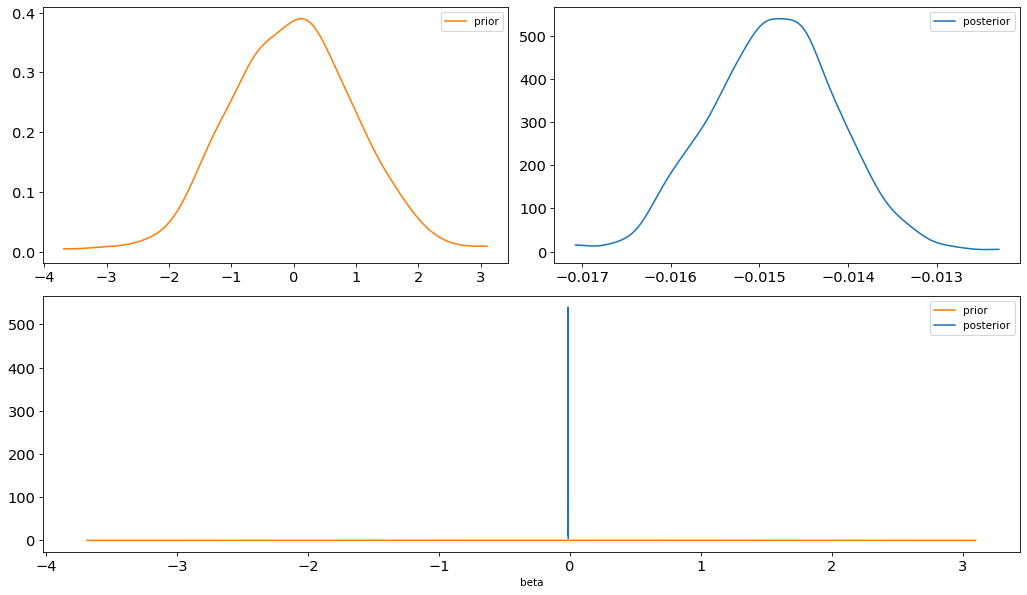
Looking at the posterior distributions of alpha and beta, we can see that they fall comfortably within the prior distributions of these parameters, which means that the priors didn’t have much effect on the results.
As an experiment, try increasing or decreasing the standard deviations of the priors and see what effect it has on the posterior distributions.
Sampling diagnostics#
After sampling, we want to check that the process worked well — meaning:
All chains have effectively explored the posterior distribution, and
Successive draws within each chain are only weakly correlated (each draw should provide mostly new information).
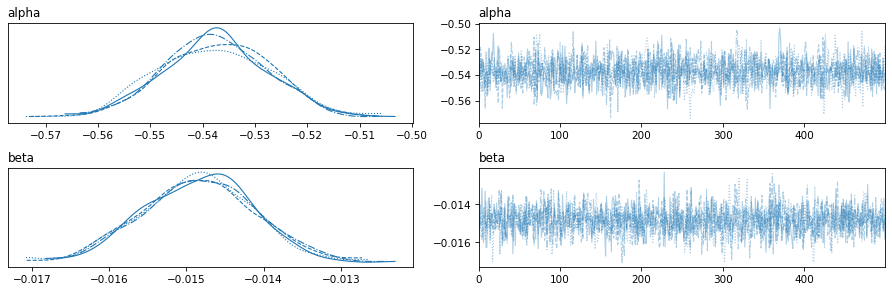
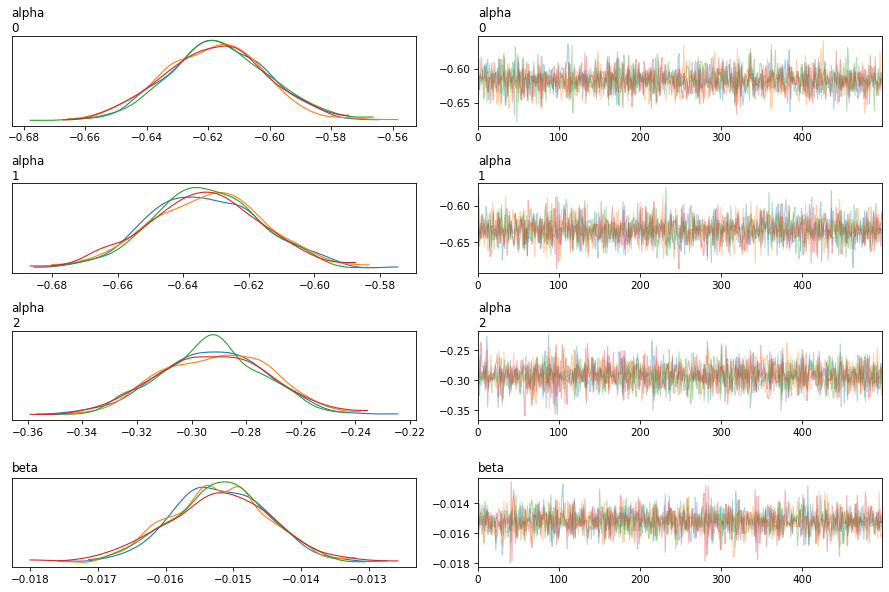
We can check these properties visually using plot_trace:
On the left, the distribution from each chain should look similar — this is evidence that the chains all converged to the same region of the posterior.
On the right, the sequence of draws within each chain should look like uncorrelated noise (sometimes called “hairy caterpillars”). It shouldn’t look like a random walk and there shouldn’t be flat spots, which would suggest the chain got stuck.
az.plot_trace(idata, var_names=["alpha", "beta"])
decorate()
To check these properties numerically, we can look at two key summary statistics: ESS and r-hat.
r-hat quantifies the difference between chains. If all chains converged to the same posterior distribution, r-hat should be close to 1. If the chains are exploring different regions, r-hat will be larger than 1, indicating failure to converge.
Effective Sample Size (ESS) tells us how much independent information the draws actually contribute. If successive values within a chain are highly correlated, the chain isn’t exploring the posterior efficiently, and ESS will be smaller than the total number of draws.
az.summary(idata)
| mean | sd | hdi_3% | hdi_97% | mcse_mean | mcse_sd | ess_bulk | ess_tail | r_hat | |
|---|---|---|---|---|---|---|---|---|---|
| alpha | -0.537 | 0.010 | -0.556 | -0.518 | 0.0 | 0.0 | 1790.0 | 1395.0 | 1.01 |
| beta | -0.015 | 0.001 | -0.016 | -0.014 | 0.0 | 0.0 | 2218.0 | 1451.0 | 1.00 |
Generating predictions#
There are two ways to generate predictions:
We can use the results from PyMC to compute our own predictions.
We can use the PyMC model.
With this example, we’ll demonstrate the first way.
First, we’ll extract the samples of the coefficients from idata and convert them to NumPy arrays.
# Collect posterior draws of alpha and beta
samples = az.extract(idata, var_names=["alpha", "beta"], num_samples=100)

alphas = samples["alpha"].to_numpy()
alphas.shape
(100,)
betas = samples["beta"].to_numpy()
betas.shape
(100,)
Here’s the range of years we’ll predict.
year_range = np.arange(1970, 2031)
year_centered = year_range - year_shift
To generate predictions, we pretty much reimplement the model in NumPy.
from scipy.special import expit

for alpha, beta in zip(alphas, betas):
    zs = alpha + beta * year_centered
    probs = expit(zs) * 100
    plt.plot(year_range, probs, color="C0", alpha=0.02)

time_series.plot(style="o", label="observed")
decorate(ylabel="percent", title="Percent saying people can be trusted")
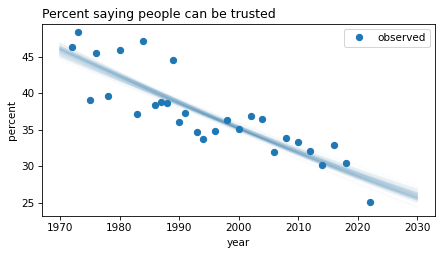
It looks like the model fits the data well, and makes a plausible projection for the future.
Centering the Data#
You might remember that we mean-centered the predictor, year.
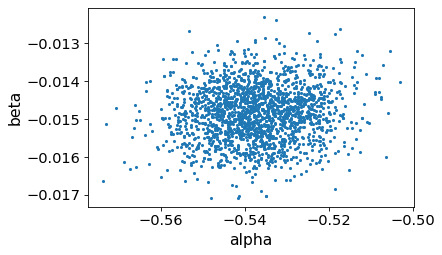
Now here’s why: because we centered year, the sampled slopes and intercepts are uncorrelated.
az.plot_pair(idata, var_names=["alpha", "beta"])
decorate()
As an experiment, try:
Set
year_shift=1970and run the model again. You might get some warnings from the sampler, andplot_pairwill show that the alphas and betas are correlated. The not-quite-centered predictor stretches the shape of the joint posterior distribution and makes it harder to sample efficiently.Set
year_shift=0and run the model again. With the predictor completely uncentered, the joint posterior distribution is so stretched that the sampler diverges frequently – and basically fails.
Without centering, the intercept represents the log-odds of the outcome when year=0, which is way outside the range of the data.
This forces the intercept and slope to compensate for each other — if the slope increases, the intercept must decrease to hit the same observed points.
As a general rule, it’s a good idea to center continuous predictors in Bayesian regression models.
Categorical predictors#
Now let’s add political party as a predictor.
value_counts(gss["partyid3"])
| counts | |
|---|---|
| values | |
| 0.0 | 25439 |
| 1.0 | 26705 |
| 2.0 | 18338 |
| NaN | 1908 |
To prepare the data, we’ll select observations where all the variables in the model are valid.
data = gss.dropna(subset=["y", "year", "partyid3"])
data = subsample(data)
data.shape
(41605, 64)
And again we’ll center the years and convert all data to NumPy arrays.
y = data["y"].to_numpy()

year = data["year"].to_numpy()
year_shift = data["year"].mean()
year = year - year_shift

partyid3 = data["partyid3"].astype(int).to_numpy()
This version of the model adds a separate intercept for each group, but still has a single coefficient for the year effect.
# Modify this

with pm.Model() as logistic_model2:

    # Priors for intercept and slope
    alpha = pm.Normal("alpha", 0, 1)
    beta = pm.Normal("beta", 0, 1)

    # Linear predictor (log-odds)
    z = alpha + beta * year

    # The inverse logit function is called sigma
    p = pm.math.sigmoid(z)

    # Bernoulli likelihood with logit link
    y_obs = pm.Bernoulli("y_obs", p=p, observed=y)
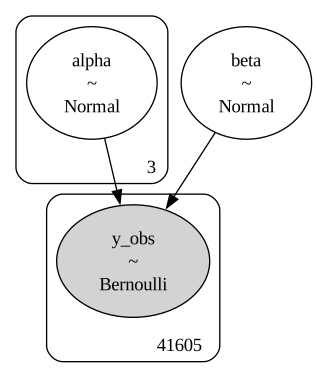
Here’s the graph representation of the model.
pm.model_to_graphviz(logistic_model2)
And here’s how we run the sampler.
filename = 'logistic_model2_idata.nc'
idata2 = load_idata_or_sample(logistic_model2, filename, draws=500, tune=500)
Loaded idata from logistic_model2_idata.nc
Here are the trace plots.
az.plot_trace(idata2, compact=False, var_names=["alpha", "beta"])
decorate()
And the diagnostic statistics.
az.summary(idata2, var_names=["alpha", "beta"])
| mean | sd | hdi_3% | hdi_97% | mcse_mean | mcse_sd | ess_bulk | ess_tail | r_hat | |
|---|---|---|---|---|---|---|---|---|---|
| alpha[0] | -0.617 | 0.017 | -0.648 | -0.585 | 0.0 | 0.0 | 3186.0 | 1500.0 | 1.00 |
| alpha[1] | -0.633 | 0.017 | -0.665 | -0.601 | 0.0 | 0.0 | 3125.0 | 1526.0 | 1.00 |
| alpha[2] | -0.292 | 0.020 | -0.330 | -0.257 | 0.0 | 0.0 | 3141.0 | 1470.0 | 1.01 |
| beta | -0.015 | 0.001 | -0.017 | -0.014 | 0.0 | 0.0 | 3040.0 | 1569.0 | 1.00 |
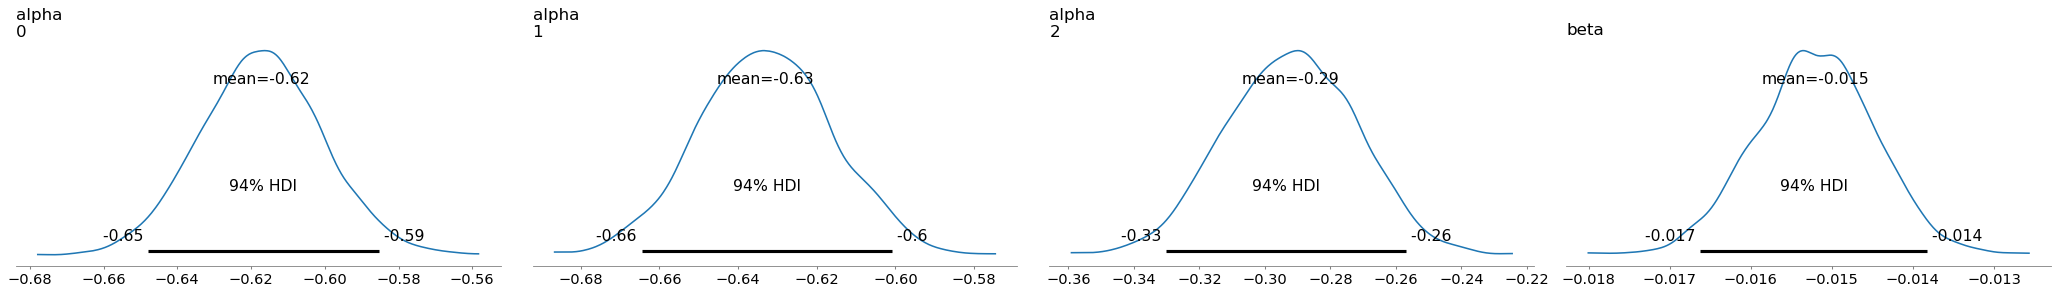
Here are the posteriors.
az.plot_posterior(idata2)
decorate()
Viewing the Results#
# Collect posterior draws of alpha and beta
samples = az.extract(idata2, var_names=["alpha", "beta"], num_samples=100)

alphas = samples["alpha"].to_numpy()
alphas.shape
(3, 100)
betas = samples["beta"].to_numpy()
betas.shape
(100,)
Here’s the range of years we’ll predict.
year_range = np.arange(1970, 2031)
year_centered = year_range - year_shift
Now we can plot the results for the three groups.
table.plot(color=colors)

for i in range(3):
    for alpha, beta in zip(alphas[i], betas):
        logits = alpha + beta * year_centered
        probs = expit(logits) * 100
        plt.plot(year_range, probs, color=colors[i], alpha=0.02)

decorate(ylabel="percent", title="Percent saying people can be trusted")
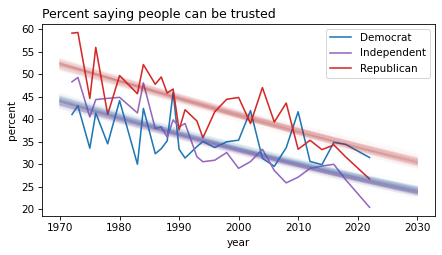
The posterior distributions of p overlap for the Democrat and Independent groups, but the distribution for Republicans is notably different.
Based on these results, we can say with some confidence that Republicans are more likely to say people can be trusted – at least under the assumption that the changes over time are well modeled by the logistic regression model.
Let the Model Do the Work#
It might seem silly that we have to implement the model twice, once in PyMC to generate the posterior distribution, and once in NumPy to interpret the results.
It is possible – and often desirable – to make the PyMC model do the work, but for that we’ll need two additional features:
Data, which makes the input data part of the model so we can modify it to make out-of-sample predictions, andDeterministic, which saves the result of intermediate calculations as part of theInferenceData.
Here’s the augmented version of the previous model.
with pm.Model() as logistic_model3:

    # add the predictors to the model as Data
    year_pt = pm.Data("year", year)
    partyid3_pt = pm.Data("partyid3", partyid3)

    # Party-specific intercepts (one for each group)
    alpha = pm.Normal("alpha", 0, 1, shape=3)

    # Shared slope for year (assuming effect of year is the same across parties)
    beta = pm.Normal("beta", 0, 1)

    # Linear predictor (log-odds)
    z = alpha[partyid3_pt] + beta * year_pt

    # Compute and save the probabilities
    p = pm.Deterministic("p", pm.math.sigmoid(z))

    # Bernoulli likelihood
    y_obs = pm.Bernoulli("y_obs", p=p, observed=y)
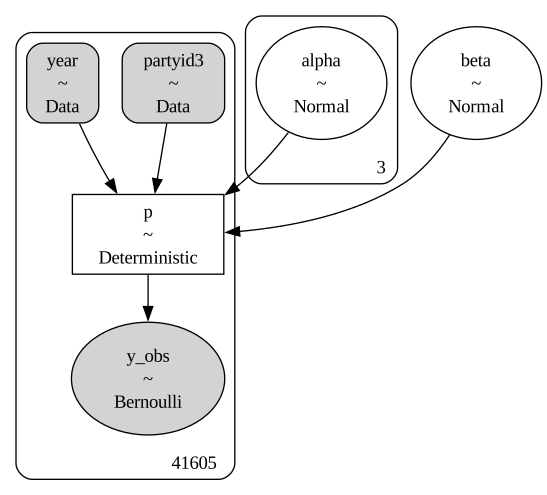
Here’s the graph representation.
pm.model_to_graphviz(logistic_model3)
And here’s how we run the sampler.
filename = 'logistic_model3_idata.nc'
idata3 = load_idata_or_sample(
    logistic_model3, filename, draws=500, tune=500, var_names=["alpha", "beta"]
)
Loaded idata from logistic_model3_idata.nc
Everything marked as Deterministic gets saved in the idata.
idata3
-
<xarray.Dataset> Size: 68kB Dimensions: (chain: 4, draw: 500, alpha_dim_0: 3) Coordinates: * chain (chain) int64 32B 0 1 2 3 * draw (draw) int64 4kB 0 1 2 3 4 5 6 ... 493 494 495 496 497 498 499 * alpha_dim_0 (alpha_dim_0) int64 24B 0 1 2 Data variables: alpha (chain, draw, alpha_dim_0) float64 48kB ... beta (chain, draw) float64 16kB ... Attributes: created_at: 2026-10-21T13:40:42.443993+00:00 arviz_version: 0.23.4 inference_library: nutpie inference_library_version: 0.16.11 sampling_time: 8.922820329666138 tuning_steps: 500 -
<xarray.Dataset> Size: 282kB Dimensions: (chain: 4, draw: 500) Coordinates: * chain (chain) int64 32B 0 1 2 3 * draw (draw) int64 4kB 0 1 2 3 4 ... 495 496 497 498 499 Data variables: (12/20) depth (chain, draw) uint64 16kB ... maxdepth_reached (chain, draw) bool 2kB ... step_size (chain, draw) float64 16kB ... transformation_update_id (chain, draw) int64 16kB ... step_size_bar (chain, draw) float64 16kB ... mean_tree_accept (chain, draw) float64 16kB ... ... ... fisher_distance (chain, draw) float64 16kB ... transformation_index (chain, draw) int64 16kB ... diverging (chain, draw) bool 2kB ... divergence_draw (chain, draw) uint64 16kB ... divergence_message (chain, draw) float64 16kB ... divergence_energy_error (chain, draw) float64 16kB ... Attributes: created_at: 2026-10-21T13:40:42.424825+00:00 arviz_version: 0.23.4 -
<xarray.Dataset> Size: 666kB Dimensions: (y_obs_dim_0: 41605) Coordinates: * y_obs_dim_0 (y_obs_dim_0) int64 333kB 0 1 2 3 4 ... 41601 41602 41603 41604 Data variables: y_obs (y_obs_dim_0) int64 333kB ... Attributes: created_at: 2026-10-21T13:40:42.443299+00:00 arviz_version: 0.23.4 inference_library: pymc inference_library_version: 5.28.5 -
<xarray.Dataset> Size: 1MB Dimensions: (year_dim_0: 41605, partyid3_dim_0: 41605) Coordinates: * year_dim_0 (year_dim_0) int64 333kB 0 1 2 3 ... 41601 41602 41603 41604 * partyid3_dim_0 (partyid3_dim_0) int64 333kB 0 1 2 3 ... 41602 41603 41604 Data variables: year (year_dim_0) float64 333kB ... partyid3 (partyid3_dim_0) int32 166kB ... Attributes: created_at: 2026-10-21T13:40:42.442008+00:00 arviz_version: 0.23.4 inference_library: pymc inference_library_version: 5.28.5 -
<xarray.Dataset> Size: 68kB Dimensions: (chain: 4, draw: 500, alpha_dim_0: 3) Coordinates: * chain (chain) int64 32B 0 1 2 3 * draw (draw) int64 4kB 0 1 2 3 4 5 6 ... 493 494 495 496 497 498 499 * alpha_dim_0 (alpha_dim_0) int64 24B 0 1 2 Data variables: alpha (chain, draw, alpha_dim_0) float64 48kB ... beta (chain, draw) float64 16kB ... Attributes: created_at: 2026-10-21T13:40:42.414790+00:00 arviz_version: 0.23.4 -
<xarray.Dataset> Size: 658kB
Dimensions:                   (chain: 4, draw: 500)
Coordinates:
  * chain                     (chain) int64 32B 0 1 2 3
  * draw                      (draw) int64 4kB 0 1 2 3 4 ... 495 496 497 498 499
Data variables: (12/20)
    depth                     (chain, draw) uint64 16kB ...
    maxdepth_reached          (chain, draw) bool 2kB ...
    step_size                 (chain, draw) float64 16kB ...
    transformation_update_id  (chain, draw) int64 16kB ...
    step_size_bar             (chain, draw) float64 16kB ...
    mean_tree_accept          (chain, draw) float64 16kB ...
    ...                        ...
    fisher_distance           (chain, draw) float64 16kB ...
    transformation_index      (chain, draw) int64 16kB ...
    diverging                 (chain, draw) bool 2kB ...
    divergence_draw           (chain, draw) uint64 16kB ...
    divergence_message        (chain, draw) <U49 392kB ...
    divergence_energy_error   (chain, draw) float64 16kB ...
Attributes:
    created_at:     2026-10-21T13:40:42.437677+00:00
    arviz_version:  0.23.4
Now to generate predictions, we can use the PyMC model directly. We’ll use:
set_datato replace the data used during sampling with the values ofpartyid3andyearwe want to use for prediction, andcompute_deterministicsto compute the values ofp, conditioned on the posterior distributions ofalphaandbeta.
probabilities = {}

with logistic_model3:
    for key, party_name in party_names.items():
        # Set the predictors to the values we want predictions for
        pm.set_data(
            {
                "partyid3": np.tile(key, len(year_centered)),
                "year": year_centered,
            }
        )

        # Compute the probabilities
        idata = pm.compute_deterministics(idata3['posterior'])

        probabilities[party_name] = az.extract(idata, num_samples=100)["p"]
Here’s what the results look like.
# Plot the original data
table.plot(color=colors)

# Plot posterior draws for each party affiliation
for key, party_name in party_names.items():
    ps = probabilities[party_name].to_numpy() * 100
    plt.plot(year_range, ps, color=colors[key], alpha=0.02)

decorate(ylabel="percent", title="Percent saying people can be trusted")
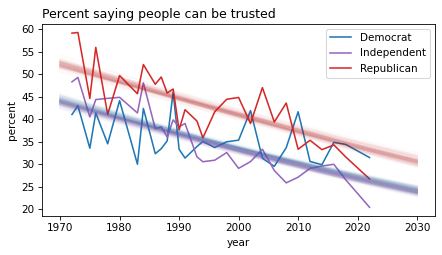
Using the PyMC model to generate predictions avoids implementing the model twice, and guarantees that the model and the predictions are consistent. The drawbacks are:
Adding
DataandDeterministiccan make the model code harder to read.Saving the
DataandDeterministicvariables makes theInferenceDatalarger.
Copyright 2025–2026 Allen B. Downey and Alexander Fengler
Code license: MIT License
Text license: Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International